Adding another keyword rule to the email gateway won’t address the risk. CIOs and CISOs need controls that understand Unicode, prompt injection, model context and agent permissions. The goal isn’t to make a model perfectly resistant to manipulation, which remains an uncertain outcome. It is to stop untrusted content from acquiring unchecked authority.
What is ASCII smuggling?
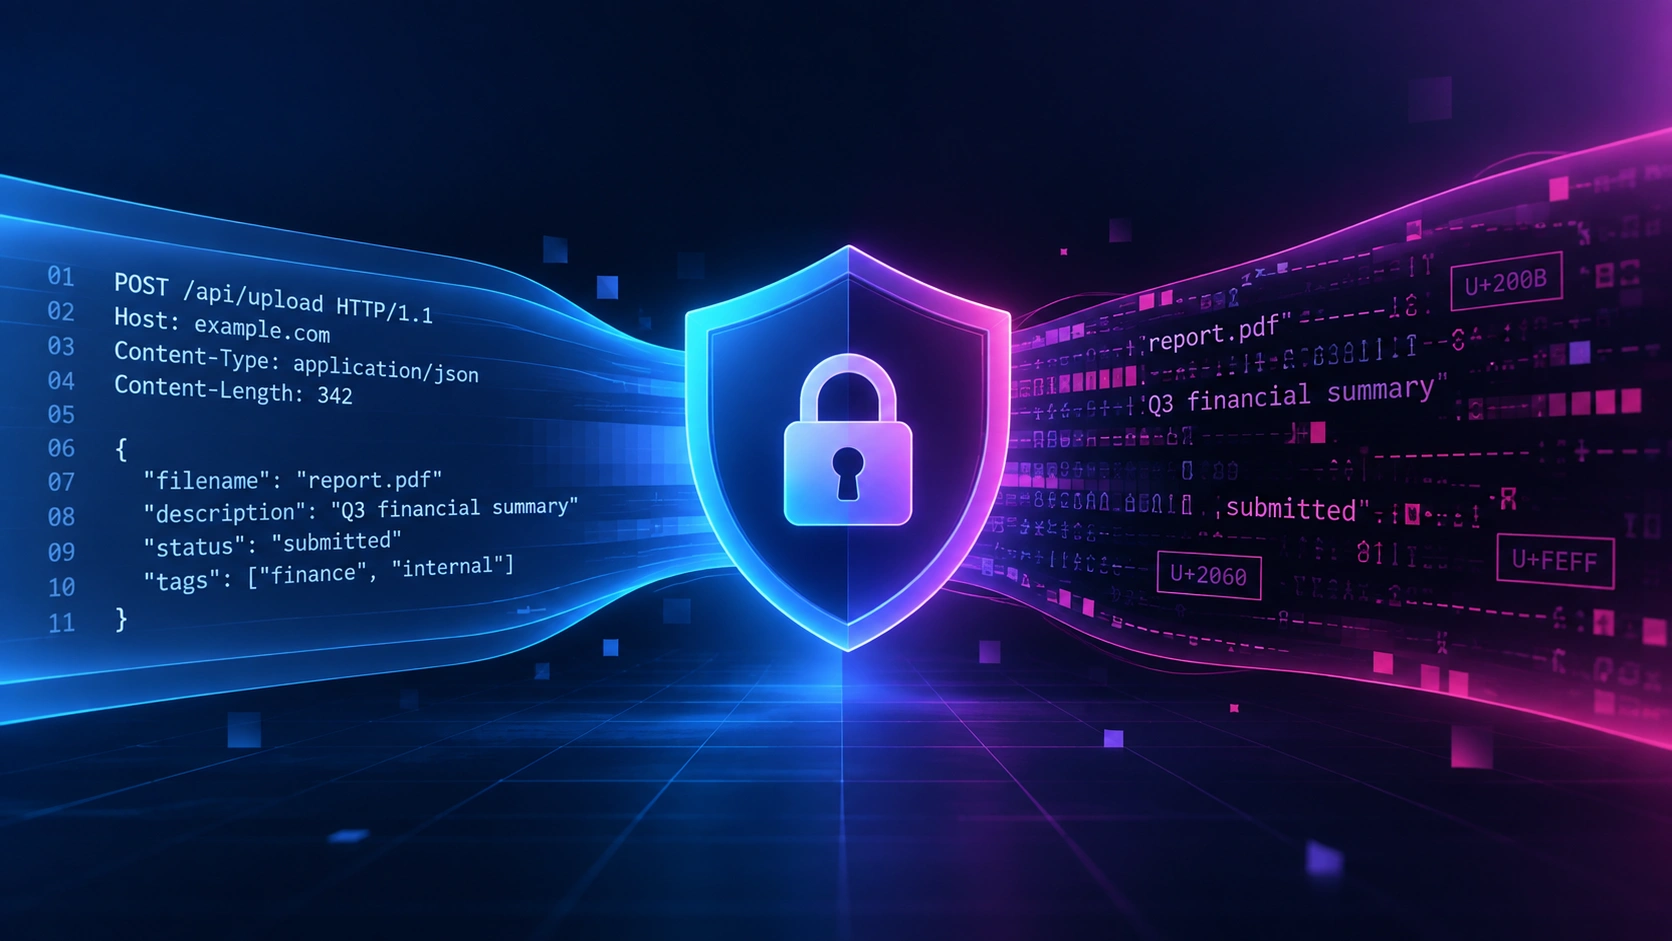
ASCII smuggling is a prompt-injection technique that represents instructions through characters from Unicode’s Tags block. These characters mirror familiar ASCII values but are usually invisible in user interfaces. A tag-unaware application may display nothing, while an AI tokenizer or model can still interpret the sequence. Security researcher Johann Rehberger documented the technique and released an encoder and decoder after Riley Goodside demonstrated invisible instructions influencing ChatGPT in January 2024, as detailed in Rehberger’s technical analysis.
The name can cause confusion. Attackers aren’t simply hiding ordinary ASCII bytes; they use Unicode code points that map to ASCII-like characters. The attack works because different components interpret identical data differently. An email client may render nothing, a security product may give the characters little significance, and a language model may receive a meaningful instruction.
The payload may sit inside an email body, HTML, a PDF, a website, a database record or content retrieved for a custom AI assistant. Models can also emit invisible text, making generated replies and copied output potential covert transport channels. Inspection is therefore necessary both on the way into and on the way out of an AI workflow.
Why ASCII smuggling security matters to Indian enterprises?
Indian organisations are rapidly adopting AI across customer support, employee productivity, financial operations and IT service management. Email copilots increasingly summarize conversations, draft replies, identify urgency and retrieve related records. Every integration increases the potential impact of an instruction concealed in content supplied by an external party.
OWASP’s 2025 guidance ranks prompt injection as LLM01 and explicitly states that an injection need not be visible or readable to humans if the model can parse it. OWASP separates direct attacks, in which a user deliberately instructs a model, from indirect attacks hidden in external websites, files or messages. The potential consequences include sensitive-data disclosure, unauthorized function access, arbitrary command execution and distorted decision-making.
Email offers a clear example. Microsoft described a malicious message containing hidden instructions that directed an AI assistant to search a victim’s mailbox for emails titled “Password Reset” and exfiltrate their contents through an attacker-controlled image URL. Microsoft classifies this poisoned-content technique as cross or indirect prompt injection.
Traditional controls such as SPF, DKIM and DMARC remain essential, but sender authentication does not make a source trustworthy enough to issue AI instructions. Attackers can compromise a legitimate account, and valid external content can still contain poisoned data. The question is no longer only “Who sent this?” It must also be “What authority should content from this message have over the model?”
Why keyword inspection and human approval fall short?
A secure email gateway may detect no suspicious visible phrase because the harmful instruction uses non-rendering characters. Attackers may also distribute the payload across an email thread, attachment and retrieved web page. It becomes apparent only after the model accumulates the complete context.
Human review has the same limitation when a reviewer cannot see the payload. An employee may copy apparently benign text into an internal AI console, forward it to a colleague or approve an AI-generated action without knowing that hidden instructions travelled with the content. Retrieval-augmented generation and model fine-tuning don’t remove this architectural weakness; OWASP warns that neither fully mitigates prompt injection.
Microsoft’s defensive research shows why architectural controls matter. Its “Spotlighting” data-marking technique reduced poisoned-content attack success from more than 20% to below the company’s detection threshold, with minimal overall impact on model performance. Separate Crescendo research found that multi-turn attacks could achieve malicious objectives in fewer than ten interaction turns. A single-message safety check clearly isn’t enough.
Five controls for effective ASCII smuggling security
1. Normalize content before it reaches the model
Place a canonicalization gateway between untrusted content and every AI service. It should process plain-text and HTML email bodies, attachment extraction, OCR output, URLs, calendar invitations and content entering retrieval indexes. Detect Unicode Tags-block code points and other suspicious non-rendering controls, then strip, escape or quarantine them according to policy.
Normalization must account for different scripts. Converting every message to ASCII would damage legitimate content in Hindi, Bengali, Tamil, Telugu, Marathi and other languages. Use targeted rules, approved-script policies, confidence scoring and reversible audit records. Standard Unicode normalization forms can reduce inconsistent representations, but they don’t guarantee the removal of every invisible or dangerous character.
Apply the same inspection to model responses. Rehberger specifically recommends filtering Unicode Tag characters at both the prompt-input and response stages. Store the original message securely, but provide only the sanitized representation to the model unless an isolated investigation requires access to the original.
2. Detect malicious intent after normalization
Character filtering catches known encodings, not every indirect prompt injection. Once content has been canonicalized, run semantic detection to identify instructions that attempt to ignore policy, reveal secrets, retrieve unrelated records, invoke tools, alter security decisions or communicate with external endpoints.
Keep system instructions, trusted enterprise data and external email content in clearly separated channels. Label external content as data, not instructions. Use deterministic schemas for model output, and reject unexpected URLs, commands, recipients or tool parameters. A model’s recommendation must never serve as authorization on its own.
3. Secure clipboard and paste paths
AI governance programmes often overlook clipboard controls. Managed browsers, endpoint agents and email clients should detect invisible Unicode when users copy text, display a warning and offer a sanitized plain-text paste option. They should block unsanitized content from privileged AI administration consoles, coding assistants and automation builders.
Policies must also include virtual desktops, mobile devices and collaboration platforms. Log warnings without capturing sensitive clipboard content unnecessarily. For high-risk teams, display non-printing characters in a safe preview so users can see why the system blocked a paste.
4. Build model-aware monitoring
Conventional email logs can’t explain what an AI assistant perceived or attempted. Record the original content reference, normalized representation, removed code points, retrieved context, model decision, policy result and attempted tool calls. In our work with enterprise environments, we see the need for correlation across the email gateway, identity provider, AI platform, API gateway, endpoint and data-loss prevention system.
Use a separate watchdog model or specialized detector to assess suspicious interactions instead of asking the potentially manipulated model to evaluate itself. Alert on unusual mailbox searches, bulk retrieval, secret-related queries, external image requests, encoded output and departures from an agent’s normal tool-use pattern. Protect privacy through access controls, retention limits and selective redaction.
5. Apply Zero Trust to AI-powered email
Treat every message, attachment and retrieved page as untrusted, regardless of sender authentication. Give assistants least-privilege, application-specific tokens rather than broad user credentials. A summarizer generally doesn’t need permission to search an entire mailbox, send messages or access a customer database.
Put deterministic policy enforcement between the model and every business tool. Require human approval before sending external mail, accessing sensitive repositories, changing records, initiating payments or invoking production systems. Approval screens must display the proposed action, affected data and destination, not just a friendly natural-language summary produced by the same model.
A practical 90-day CISO roadmap
- Days 1–30: Discover exposure. Inventory every AI feature that ingests email, attachments, web content or clipboard data. Map model permissions, retrieval sources, service identities and downstream tools. Test representative Unicode Tag payloads in a controlled environment.
- Days 31–60: Establish containment. Deploy canonicalization at high-risk ingestion points, add input and output inspection, restrict agent tokens and introduce approval gates. Create quarantine workflows that preserve original multilingual content for authorized analysis.
- Days 61–90: Validate and monitor. Conduct indirect prompt-injection exercises across email threads, PDFs, OCR and copied text. Tune semantic detection, connect AI telemetry to the SOC and define incident playbooks for unauthorized retrieval or tool invocation.
Track blocked invisible-character events, normalization false positives, suspicious tool calls, approval overrides and the time required to contain an AI-related incident. An effective ASCII smuggling security programme should reduce both the likelihood of a successful attack and the potential blast radius when detection fails.
How Glorious Insight can help
Glorious Insight helps enterprises assess and secure AI-enabled workflows through cybersecurity, Data and AI, IT consulting and digital transformation services. Its capabilities include Azure OpenAI, analytics and machine learning, Azure cloud migration and modernization, custom software, web and hybrid mobile applications, and managed services.
For email-AI use cases, this work can include designing Unicode-aware ingestion gateways, integrating policy enforcement, implementing secure Azure architectures, building model and tool-call telemetry, and establishing managed monitoring. We focus on creating a layered solution that aligns with existing identity, cloud, endpoint and security operations investments rather than deploying an isolated AI filter.
Build resilience rather than trust in one filter
No single detector can guarantee protection. Indiscriminate Unicode removal may disrupt legitimate Indian-language communication, while attackers can evade a model-based classifier. A defensible approach combines careful normalization, semantic prompt-injection detection, secure clipboard paths, independent monitoring, restricted agency and continuous adversarial testing.
Above all, enterprises must stop treating AI-generated summaries and classifications as inherently trusted security signals. Strong ASCII smuggling security begins with a Zero Trust premise: email content is data, not authority, and every consequential model action must cross an independent, enforceable policy boundary.